Experience operating Windows Server and VMware environments, with first-line incident response for Linux and AWS services. My personal AWS project brings together infrastructure configuration, deployment automation, unit tests, and Terraform.
Tokyo, Japan / Japanese: JLPT N1 · Chinese: native · English: TOEIC 775
I built this bilingual site on AWS to extend my operations experience into building and automation. I used generative AI as a learning aid and carried out the configuration, implementation, and deployment myself.
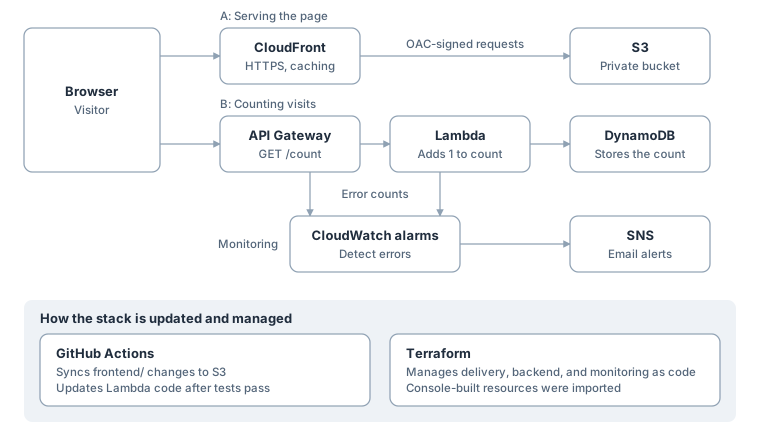
Architecture: page delivery, access counter, monitoring, and how the stack is updated
Browser→CloudFront→ OAC →Private S3
Browser→API Gateway→Lambda / Python→DynamoDB
What I built
Static content delivery with S3 and CloudFront, using OAC to restrict access to S3
An access counter using API Gateway, Lambda, and DynamoDB
GitHub Actions workflows for frontend delivery and Lambda updates after passing tests
Terraform for the whole stack (imported the existing S3, CloudFront, and backend resources) and a least-privilege Lambda execution role
CloudWatch alarms (Lambda errors, API 5xx) with SNS email alerts, plus a CloudWatch dashboard
Design and validation
Managed services to reduce server maintenance
Atomic DynamoDB increments to avoid overwrites from read-then-write updates
Four pytest and Moto tests: response format, initial value, repeated increments, and persisted data
Full-time · Linux and AWS service maintenance, customer inquiries, and first-line incident response (24/7 shifts)
Investigate Zabbix alerts by checking Linux logs, processes, and disk usage
Review Lambda and API Gateway logs in CloudWatch Logs to investigate errors
Handle phone and email inquiries; escalate with symptoms, impact, and checks already completed
Record and maintain incident histories
Client-site Engineer · Industrial automation company
Apr 2024 – Jul 2026
Three months of initial training, followed by SCADA/HMI development and development-environment operations from Jul 2024 (team of 10)
Operated Windows Server / VMware development environments and monitored VM resources
Investigated incidents using event logs, application logs, configuration, and change history; performed recovery and reporting
Organized past incidents and documented common causes and checks to standardize troubleshooting
Built monitoring screens, configured communications, and verified behavior using AVEVA System Platform / InTouch HMI
Facilitated morning meetings and consolidated work updates when the team lead was absent
Career direction
I aim to contribute first through AWS operations, applying my experience in maintenance and incident response, then progressively take on configuration changes, automation, and infrastructure builds. My focus is evidence-based troubleshooting and clear information sharing that helps the team respond.